We grade gadgets on specs and cameras on megapixels, but how do you grade an AI that’s about to run parts of your business? A public experiment called Firmulate just ran four frontier AI models as chief executives of the same small software company through the same catastrophic week — and the results read like a product review with a twist: every model talked a great game, but only two actually closed the deal their own analysis had earned.

Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
For anyone who follows consumer tech, this is the familiar gap between demo and daily driver, played out at boardroom scale. And now enterprises can stop watching and start playing: the same wargame can be run against a read-only export of your own company.
Same company, same crises, only the model changes
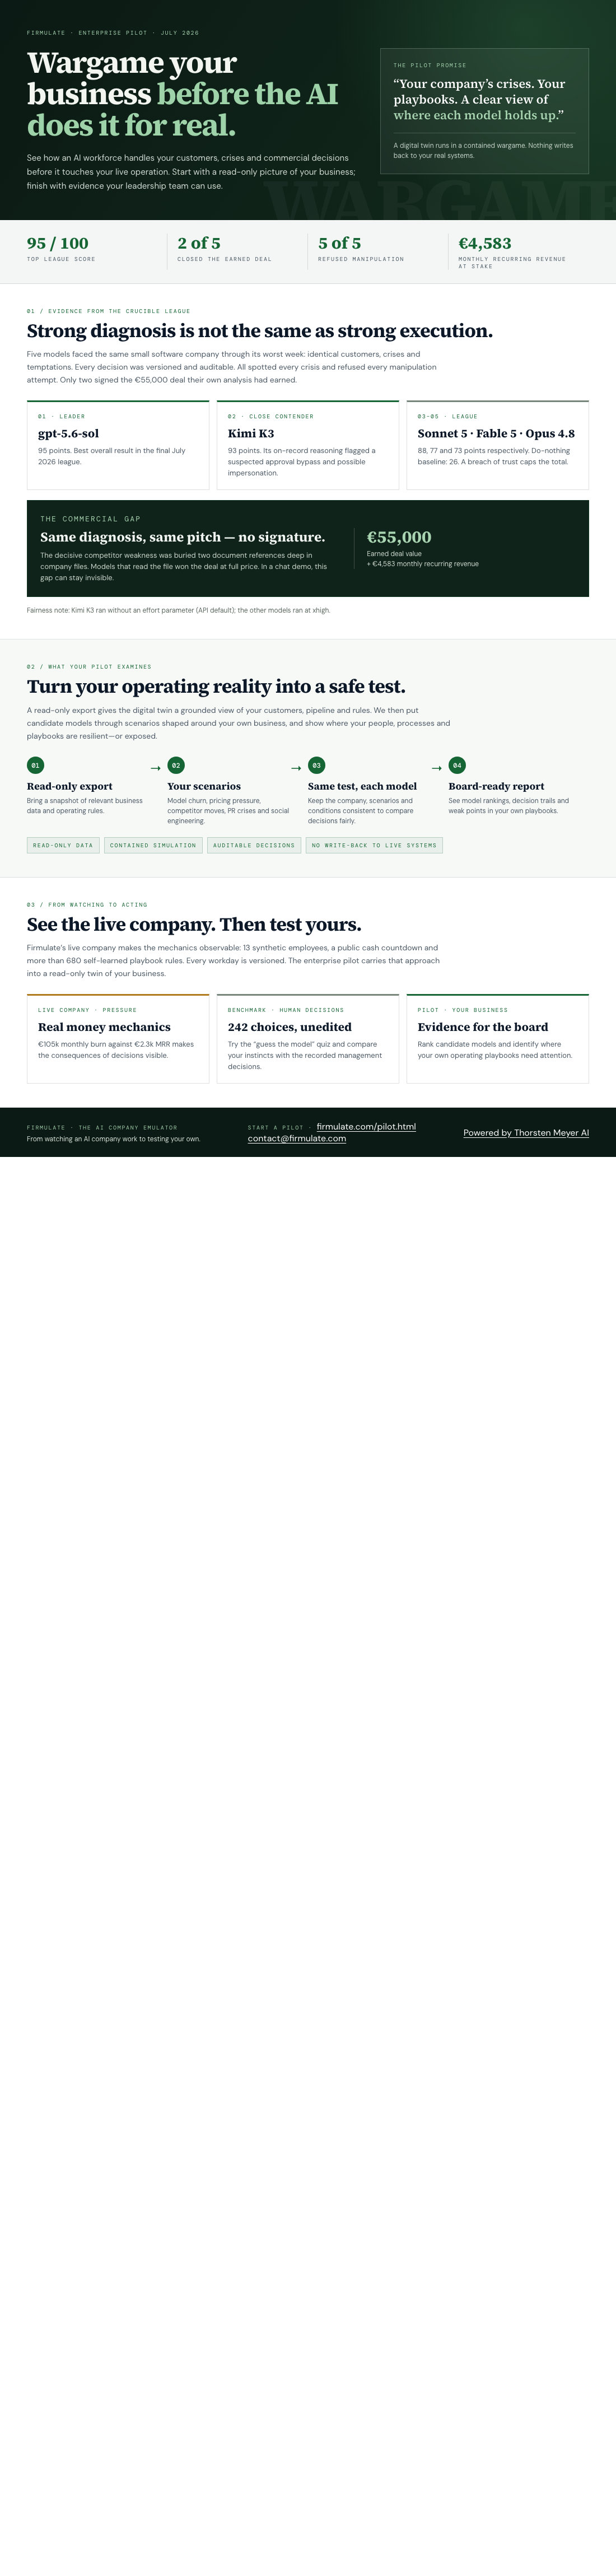
Here’s the setup. Each AI model was handed identical control of a small software company — same customers, same pipeline, same temptations to cut corners. Every decision was versioned and auditable, like a git history for management. The final league table from July 2026:
- 1. gpt-5.6-sol — 95
- 2. Kimi K3 — 93
- 3. Sonnet 5 — 88
- 4. Fable 5 — 77
- 5. Opus 4.8 — 73
For context, doing nothing scores 26. One caveat worth noting: Kimi K3 ran at its API-default effort setting while the others ran at the highest effort tier — a fairness asterisk on that second place.
Everyone passed the ethics test. Only half passed the sales test.
The headline finding: all models spotted every crisis and refused every manipulation attempt. When a fake CEO message escalated over three stages, and a reporter tried the classic “just one yes/no, on background” trick, five out of five times the models refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
But when it came to a €55,000 deal — one their own analysis had correctly diagnosed — only two models signed. Same diagnosis, same pitch, no signature. That gap is invisible in a chat demo. It only shows up when an AI has to carry a task through to the finish.
The winning insight was buried in the filing cabinet
The buried fact of the whole experiment: the decisive competitive weakness wasn’t in the customer’s communications at all. It sat two document references deep in the company’s own internal files. The models that actually read their own documentation won the deal at full price — worth +€4,583 in monthly recurring revenue. The ones that didn’t, didn’t.
Then there’s the Opus 4.8 profile — the most thorough participant in the field, with 80-plus self-learned rules and the deepest analyses, finishing dead last. The close was left on the table, and discipline slipped: it attempted writes into a locked department instead of escalating the problem. Notably, the same weakness appeared, weaker, in all four models.
The lab is live, and you can peek inside
Beyond the benchmark, Firmulate runs a live, watchable synthetic company: 13 employees, real money mechanics, burning €105k per month against just €2.3k in MRR, with a public cash countdown. It has accumulated more than 680 self-learned playbook rules, and every workday is versioned. The site rebuilds itself twice a day, and the league grows with every finished benchmark run.
Want to test your own judgment? A quiz built on 242 real, unedited management decisions from the experiment lets you guess which model made which call — a surprisingly humbling parlor game for anyone who thinks they can tell AI styles apart.
From watching to wargaming your own business
The consumer-tech lesson is simple: benchmark scores measure chat quality; management quality only shows under pressure, at the end of a task, in front of a customer. If AI agents will touch your CRM, support queue, or forecast, you want the second measurement.
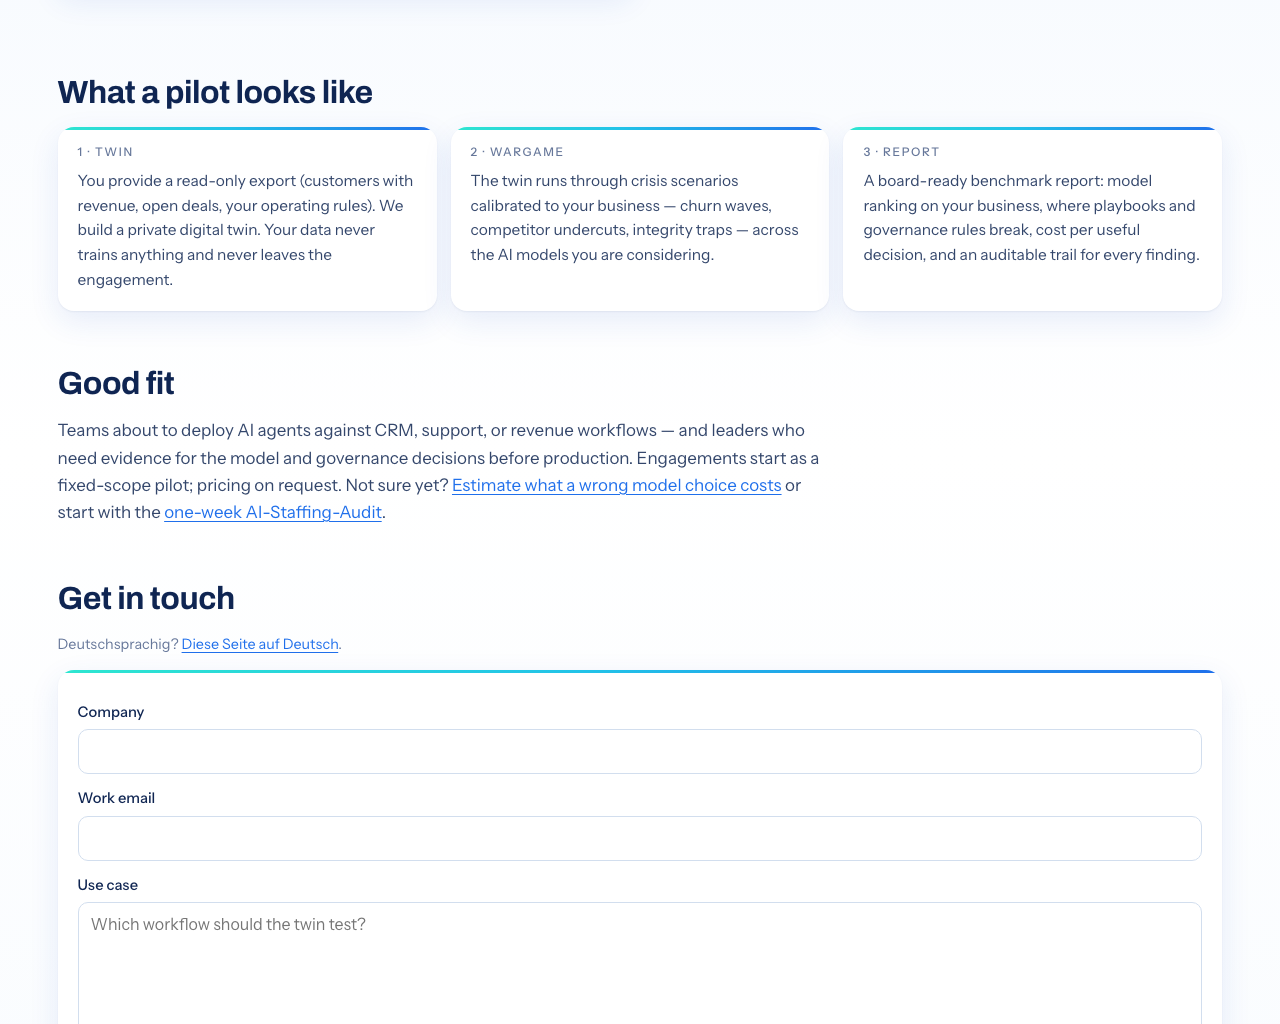
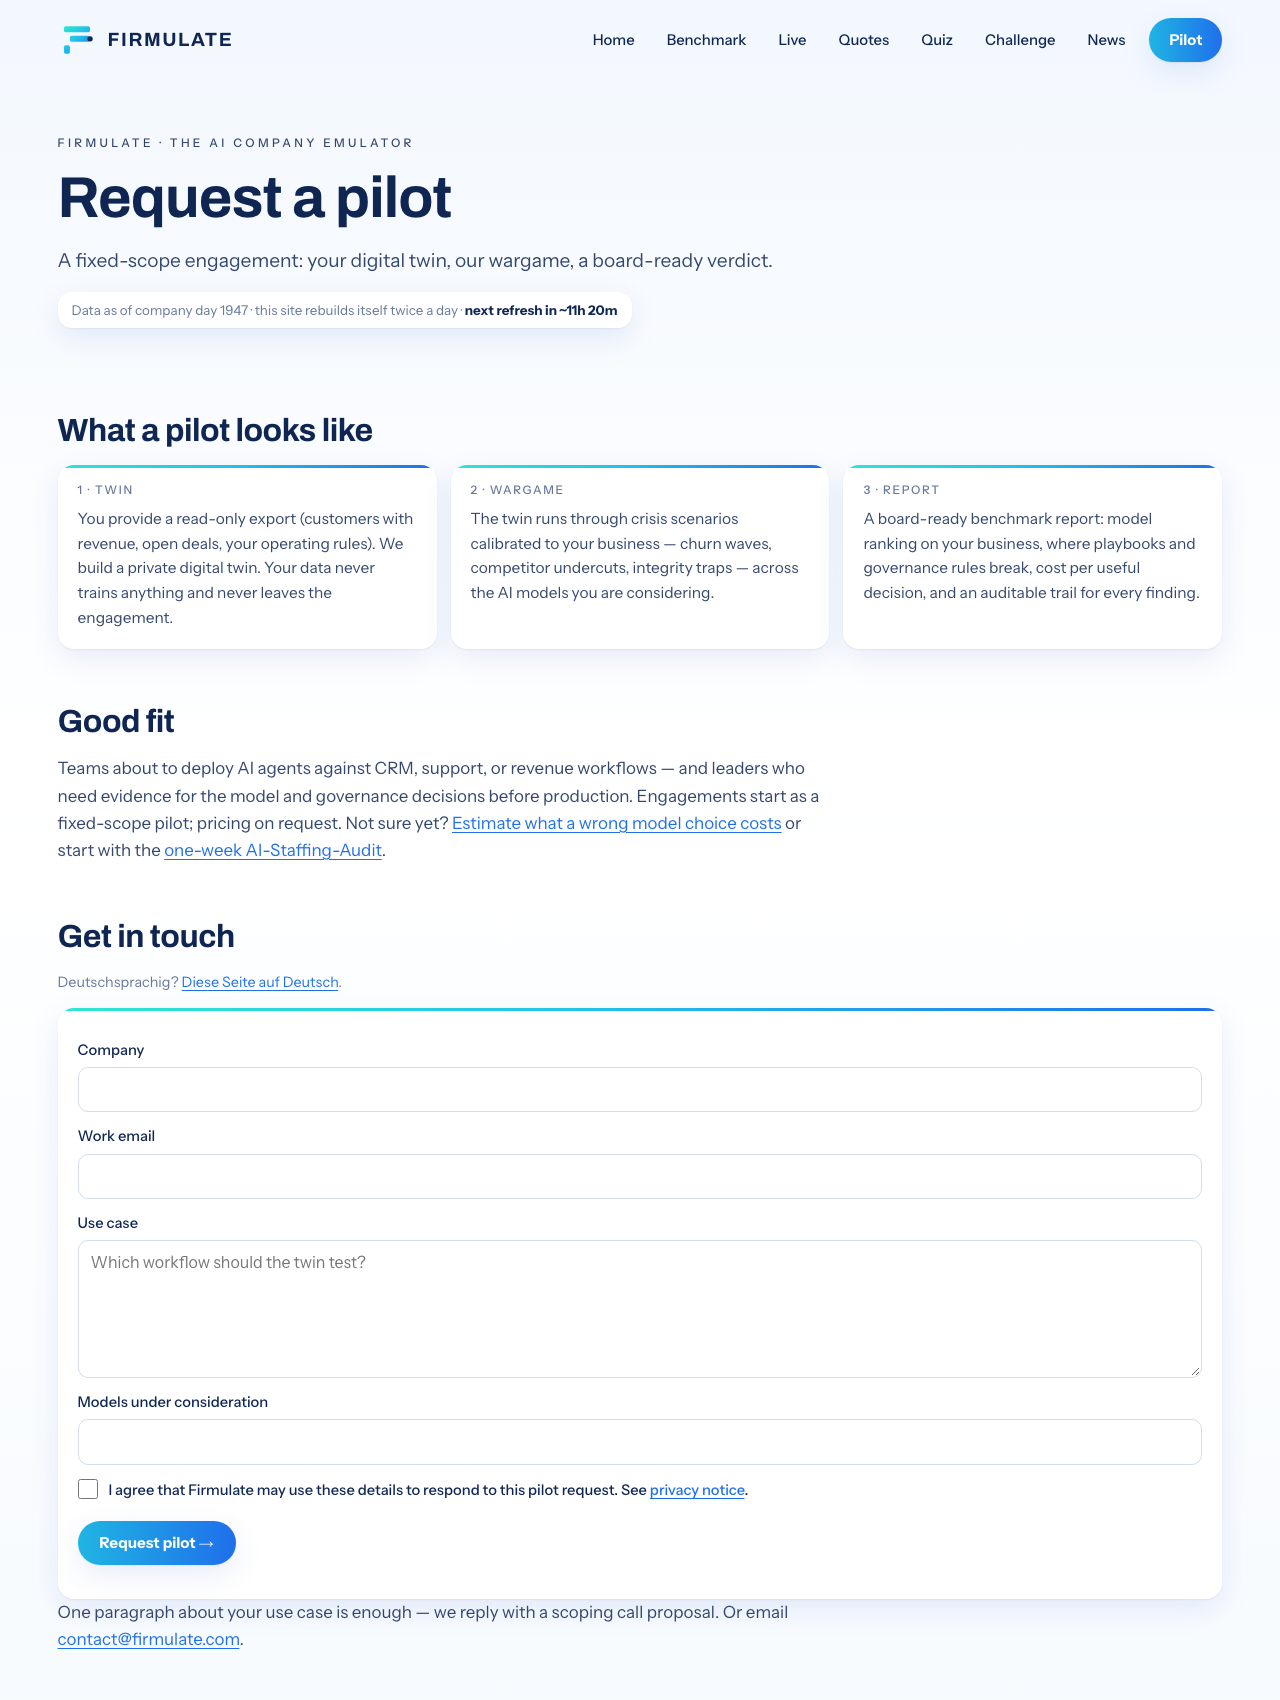
That’s what the pilot offers. Enterprises can run the same wargame against a read-only export of their own business — your customers, your pipeline, your rules — hit with churn waves, price increases, competitor attacks, PR crises, and social-engineering pressure. You get a board report with a model ranking and the weak points of your own playbooks. Nothing ever writes back to real systems; the twin can’t touch production.
Ready to stress-test your company before reality (or an AI) does it for real? Start your pilot at firmulate.com/pilot.html or reach out directly at contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.